Best Practices for CRM Integration Testing


An HTTP 200 response doesn’t prove your CRM has the right data. I check the saved record, mapped fields, and downstream actions - and test that retries don’t create duplicates.
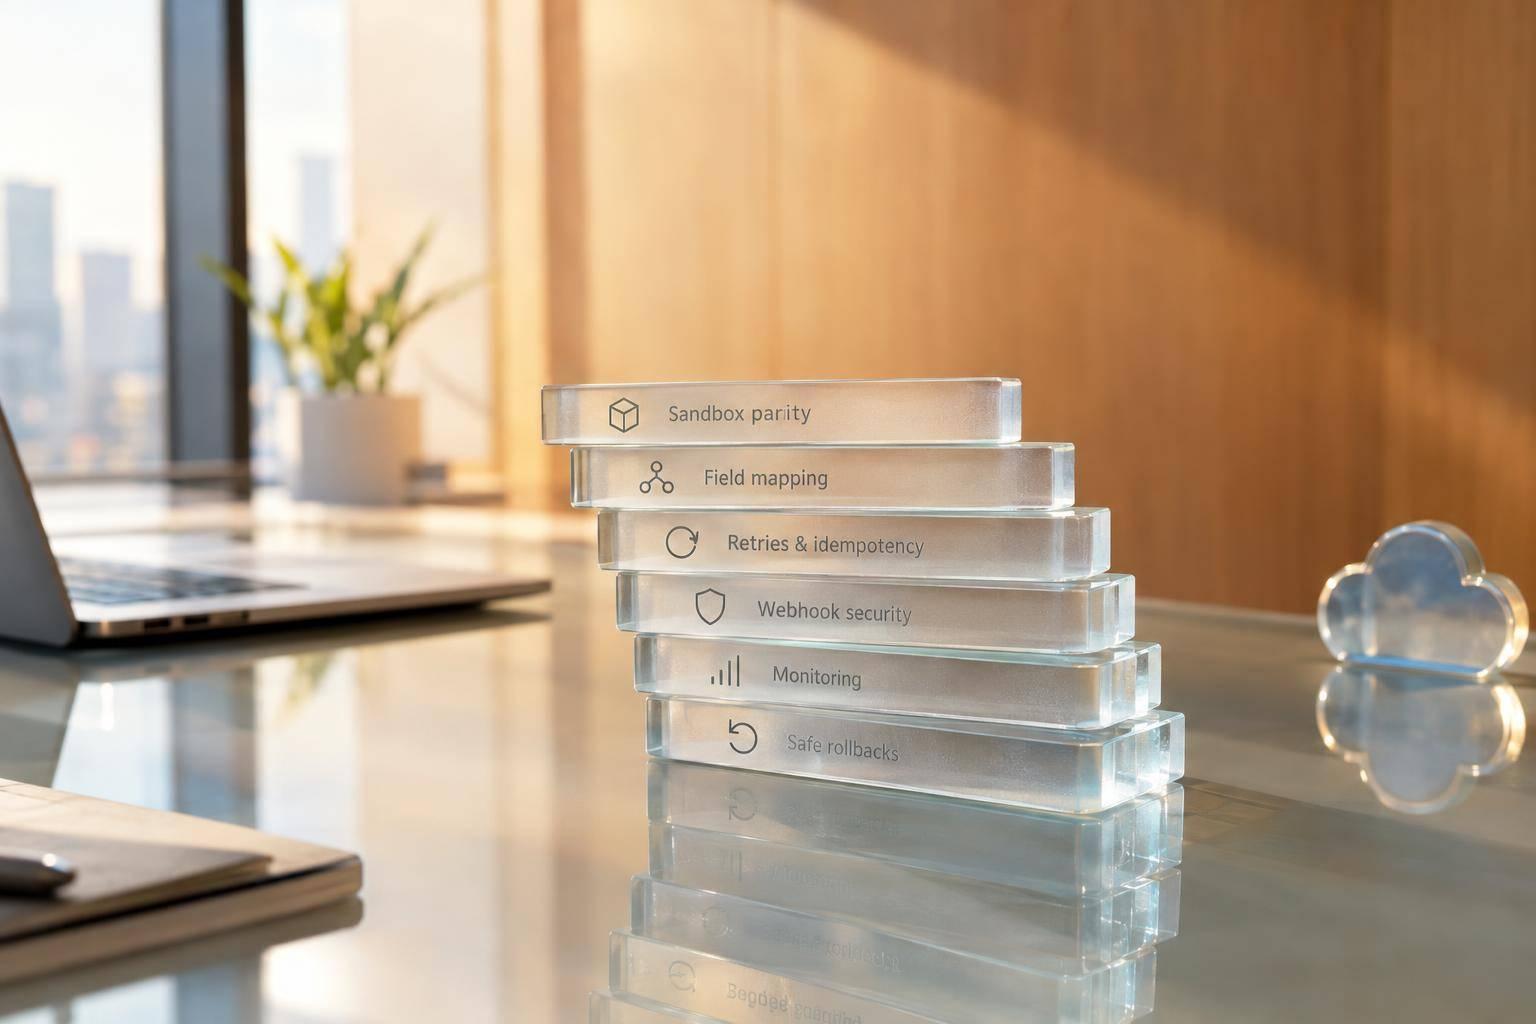
My release rule: every critical test passes, with 0 unresolved high-severity defects. Here’s what I cover:
- Scope: List systems, fields, sync directions, permissions, and pass criteria.
- Sandbox: Match production settings without putting live customer data at risk.
- Version control: Keep sanitized requests, test cases, and fixtures with the code.
- Test data: Check blanks, invalid values, field limits, and formats such as ZIP code
02108. This is especially critical when using multi-step forms to capture complex lead data. - Data checks: Verify saved values, record links, conflict rules, and sync delays.
- Failure handling: Test timeouts, bounded retries, duplicate prevention, and failed-event replay.
- Webhooks: Check signatures, event order, duplicate deliveries, missed events, and sync loops.
- Monitoring: Verify safe logs, sync metrics, and alerts that reach the right owner.
- Release and recovery: Test rollout gates, rollback, and reconciliation before replaying records.
The goal is simple: <u>prove the right change reaches the right record - even when something fails.</u>

CRM Integration Testing: From Scope to Safe Release
CRM/ERP Integration Testing
sbb-itb-5f36581
Define the CRM Integration Test Scope
Build an integration inventory before writing test cases. For each connection, record the environment, API version, endpoint, method, CRM object, trigger, authentication method, sync direction, permissions, rate limits, expected responses, and flow owner. Include custom objects, relationships, scheduled syncs, and webhooks. Record the credential type, but never put secrets in source code, fixtures, logs, or URLs.
Add a field-mapping matrix that lists each source field, destination field, data type, required status, transformation, default, and behavior for blank or invalid values. Check duplicate IDs, character limits, allowed values, time zones, and currency precision. For bidirectional syncs, define who owns each field, how to resolve conflicts, and how to prevent loops.
Separate test coverage by purpose:
- Unit tests check mapping, validation, and retry logic offline.
- Integration tests make real sandbox calls to check authentication, API contracts, and saved data.
- Regression tests rerun established cases after code, configuration, or API changes.
- End-to-end tests check a small set of complete business workflows across connected systems.
Test failure scenarios from the start, including expired tokens, insufficient permissions, malformed payloads, rate limits, timeouts, partial updates, and duplicate webhook events. Set observable pass criteria for each critical flow: correct record IDs and field values, no duplicates after retries, and complete error logs. Every critical scenario must pass, with no unresolved high-severity defects.
Run create, update, delete, and event-trigger flows in staging or a CRM sandbox first, using representative data, permissions, validation rules, and automation. Use the scope to build a sandbox that matches production settings.
1. Set Up a Production-Like CRM Sandbox
Once you’ve defined the scope, build a sandbox that matches production routing and automation. Mirror configuration, not just fields. Copy field definitions, required-field rules, routing rules, ownership checks, SLA timers, exception queues, and fallback routes. Include automation state transitions and API settings, such as pagination behavior and webhook signature validation. If the configuration is wrong, test results can mislead you: a sync may succeed but still send a lead to the wrong place.
Store secrets in a vault and grant each integration only the scopes it needs. Check that allowed actions succeed and blocked actions fail. A successful login doesn’t prove either. Keep these sandbox and production differences visible during testing.
| Area | Sandbox | Production |
|---|---|---|
| Data risk | Masked, sampled, or synthetic data | Live customer and financial data |
| Configuration fidelity | Mirrors relevant metadata; refreshes may disable jobs and endpoints | Authoritative active configuration |
| Access controls | Separate client registrations, credentials, and endpoints; limited access | Production-only credentials; audited access |
| Release readiness | Smoke, contract, and failure tests | Final deployment and live monitoring |
For release validation, maintain a post-refresh checklist covering jobs, permissions, endpoints, and restored workflows or triggers. Record known differences, including rate limits and data volume, so passing sandbox tests isn’t mistaken for matching production conditions.
2. Keep Test Plans and API Requests in Version Control
Once the sandbox is ready, keep test assets alongside the code so CRM sync validation is repeatable. Store API requests, test scripts, fixtures, mappings, schemas, templates, mock webhook payloads, and CI scripts in the repository. Commit related code, request, and fixture changes together. Tag release baselines so every result points to a specific code and test snapshot.
Commit only sanitized requests and templates. Use placeholders such as {{base_url}}, {{crm_account_id}}, and {{access_token}}, then inject live values at runtime. Scan pull requests for exposed secrets. Remove sensitive lead data from request bodies, responses, and debugging scripts - not just configuration files.
Give each test a stable requirement ID. Record its API version, endpoint and method, sanitized request body, user role, expected HTTP status, expected response fields and CRM record changes, retry outcome, cleanup steps, and acceptance criteria. A passing HTTP response isn't enough if mapped field values or duplicate-prevention behavior are wrong.
Test more than the happy path. Include positive, negative, boundary, and role-based cases: valid updates, missing required fields, malformed JSON, maximum field lengths, and read-only users. For response fixtures, check required fields, types, and error codes rather than exact timestamps or generated IDs. Label fixtures with their API version and creation date.
Use these versioned assets for repeatable CI runs. Run targeted tests on every pull request, smoke tests after sandbox deployment, and full regression tests after API, schema, mapping, auth, retry, or webhook changes. When fixing a defect, add a test that reproduces it. Confirm the test fails before the fix and passes afterward. Tie CI results to the reviewed commit so release approval points to the code and test baseline.
3. Prepare Safe Test Data
Start with the field-mapping matrix to build synthetic records. If you reuse production data, anonymize it before importing it into the sandbox.
Include incomplete submissions, duplicates, malformed values, invalid emails, and U.S. phone-format edge cases. Keep valid and invalid records separate. For phone fields, test parentheses, spaces, country codes, and conversion to E.164.
Separate display values from API values in your test fixtures. Use these U.S. fixtures to check CRM conversions:
Field Hypothetical value What to verify Date 10/25/2026Verify ISO 8601 conversion. ZIP code 02108Preserve it as a string, including the leading zero. Currency $1,234.56Strip display formatting and preserve precision in the API’s required decimal or minor-unit format. External ID EXT-000123Preserve the exact string across repeated syncs.
Check timestamps separately for time zone alignment. Test both small and large currency amounts for rounding errors.
Treat missing, null, and empty values as separate cases. Test values at each field limit and just beyond it to check encoding and truncation. Reuse stable external IDs so repeated syncs update the same record rather than create duplicates. These tests help you spot mapping errors before validating field syncs.
4. Check Field Mappings and CRM Data
Check the CRM record, not just the API response. Once test data is in place, create records through the API and read them back after create, update, and webhook events. Compare the stored values and record relationships with the expected schema.
Use these checks to tell mapping failures apart from duplicate records and timing problems:
| Integration issue | Assertion or metric |
|---|---|
| Mapping errors | Check field names, types, limits, picklists, and transformed values against the approved schema. Confirm that referenced records exist. |
| Duplicates | Repeat the same operation with the same unique identifier. Confirm that only one CRM record exists. |
| Sync lag | Measure the time from the event to the confirmed CRM update. Compare it with your sync-lag limit. |
After confirming record integrity, test how the integration handles conflicting updates. Define one source of truth for each field. Don’t assume one system owns every value.
Send conflicting updates in both directions in quick succession, vary their arrival order, and read both systems after processing. Check that the designated source wins and late events don’t overwrite newer values. Record precise event and update timestamps so failures point to the cause: mapping, conflict handling, or sync delay.
5. Test Error Handling, Retries, and Idempotency
Once mapping and data checks pass, test the failure paths. Inject invalid or expired credentials, missing required fields, malformed JSON, unavailable endpoints, connection resets, timeouts, HTTP 429 responses, and 5xx failures. Retry only transient errors on an explicit allowlist. Fail fast on validation and authorization errors. For each case, define the retry allowlist, expected attempt count, final state, and user message.
Verify bounded exponential backoff with jitter: delays should increase, timing should vary randomly, and retries should stop at a fixed attempt or time limit. Run concurrent workers to check that jitter prevents synchronized retries. Test 429 responses with Retry-After: 30, an HTTP-date value, and missing or invalid headers. Verify that missing or invalid headers trigger the bounded retry policy.
With retry limits in place, simulate a timeout after the CRM commits a write but before the client receives confirmation. Treat the result as unknown, not failed. Before retrying, reconcile it using the original idempotency key or another stable operation ID. Reuse the same idempotency key for every retry, and verify that only one logical change occurs - without duplicate CRM records or repeated downstream workflow actions.
If recovery still fails, send exhausted retries and non-retryable events to a durable dead-letter queue. Store the replayable event reference, correlation ID, failure category, attempt count, and timestamps. Leave out credentials and unnecessary personal data, and verify that the item survives a worker restart. After fixing the cause, replay duplicates and concurrent events using the original operation identity. Expect one intended change or an explicit conflict.
Keep recovery handling separate from user-facing messages, and test those messages separately from protected diagnostic logs. Tell users whether to correct a field, reconnect authorization, or wait for an automatic retry. Include a correlation ID and a clear support path when relevant. Never expose tokens, stack traces, internal URLs, or sensitive response bodies.
6. Check Webhook Security and Event Processing
After testing retry logic, check the webhook entry point that starts the sync. This is critical when connecting your marketing and sales tech stack.
Verify the sender before parsing the payload. Read the raw body, compute the HMAC, compare signatures in constant time, and reject invalid requests before any side effects occur. Test timestamp checks and event-ID deduplication together.
Authenticate and queue accepted events before returning 2xx, then process CRM updates asynchronously. Test whether acknowledgment meets the provider’s deadline when the CRM is slow or the queue is down. Document which response codes trigger retries.
Once a request passes verification, test event ordering, deduplication, and downstream processing.
| Failure condition | Expected response | Validation evidence |
|---|---|---|
| Duplicate or replayed delivery | Recognize the stable event ID; acknowledge once | Concurrent deliveries produce one CRM change; duplicate receipt is logged |
| Delayed or out-of-order event | Compare event versions; defer dependent events or refetch current data | Older payload cannot overwrite newer values |
| Processing failure | Retry queued work within limits; log the final outcome | The queue record survives a worker restart; attempt history shows the final outcome |
| Missing event | Detect through reconciliation and safely backfill | Withheld delivery is recovered; source and CRM records match |
| Sync loop | Suppress equivalent reflected updates using source markers and state comparison | Correlation trace shows one update, not a repeating loop |
| Invalid or stale signature | Reject before business processing | Modified payloads, missing or malformed signatures, wrong secrets, and expired or future-dated timestamps cause no CRM changes; secret rotation is tested |
| Malformed payload | Reject or quarantine under the provider’s response rules | Invalid or unsupported payloads produce a validation error, not partial writes |
Enforce a unique constraint on event receipts so concurrent deliveries cannot both claim the same event. Keep receipt IDs for at least the provider’s retry period. An accepted receipt does not mean downstream processing is complete. Test recovery after a crash between acceptance and completion.
Change a record in each connected system and trace the resulting events through every hop. Verify that a reflected update changes once and stops.
7. Verify Logs, Alerts, and Sync Metrics
After validating the sync path, check that every run is visible in logs and metrics. Log each sync with structured, searchable fields: an ISO 8601 timestamp in UTC, environment, integration name and version, operation, endpoint path, HTTP status, sanitized response summary, retry count, duration in milliseconds, and outcome. Record internal and CRM request IDs, along with a correlation ID that follows the transaction across services. Connect logs and traces through shared trace and span IDs.
Check redaction by searching logs for unmasked secrets or personal data. Generate synthetic sensitive values, then search the resulting logs to confirm that only approved masked or hashed values remain.
Trace one synthetic record from start to finish. Check its final status, record count, and total sync time. The completed record count should increase by exactly one. Measure sync delay from the source record’s creation or update to the CRM commit - not just the API response time.
Once baseline metrics are stable, test alert triggers one at a time: invalid credentials, controlled 429 responses, repeated 5xx errors, slow responses, stalled event delivery, duplicate processing, and stalled workers. Monitor error rate, latency, throughput, queue depth, oldest-event age, and API quota use. Zero errors don’t always mean things are working; they can also mean no events are flowing.
Set thresholds using production-like baselines and service-level objectives. Before release, check that each alert reaches its owner and includes the environment, integration, time window, current value, threshold, request ID, and runbook. Test recovery notifications, too. A sync-delay alert should clear only after processing resumes and the backlog returns to an acceptable level.
8. Test Release Checks, Rollback, and Recovery
Once logs, alerts, and sync metrics pass, run release-gate tests before any live rollout. Make critical regression tests a release gate: retest the entire path from form submission to downstream automation. Check enrichment, CRM creation or updates, record ownership, required fields, preserved UTMs, and workflow timing against agreed limits. Test missing fields, repeat submissions, partial records, and unsubscribed contacts that must stay out of active campaigns.
For forms built with Reform, test email validation, enrichment, and conditional routing. Follow the configured integration path all the way to the CRM. A successful form submission alone doesn’t prove delivery.
Set rollout gates before deployment. Move from the sandbox to a limited live rollout. Expand only when accuracy, sync success, and timing meet targets. Specify who can pause deployment or authorize rollback, and keep the previous form and mapping for 7–14 days.
If the rollout fails, rehearse rollback and replay in the sandbox. Restore the previous code and configuration together. Verify that webhook subscriptions still reach the intended endpoint, then test replay using retained events or a dead-letter queue. Rolling back code doesn’t undo CRM data changes. Reconcile affected submissions against CRM records before replaying them. Check that recovery won’t create duplicate contacts or repeat downstream actions that already ran.
Conclusion: Approve Releases With Test Results
After completing the checks above, approve a release only when the release record includes release-gate test results, source-to-CRM reconciliation, error-rate and median sync-latency metrics, alert delivery records, and rollback/recovery evidence.
For rollback and recovery sign-off, keep evidence that each submission reached the correct CRM record exactly once. Trace recovery cases using submission_id, form_version, and submitted_at. Confirm that permissions still cover post-recovery operations.
Update the test suite whenever CRM fields, API versions, authentication, workflows, or sync rules change.
FAQs
Which CRM integration tests should I automate first?
Start by automating tests for your core end-to-end lead flow in a sandbox. Use sample submissions that mirror actual lead data, and check field mappings, timestamps, and lead routing.
Then test duplicate submissions, missing required fields, and malformed data. Simulate 400 and 500 errors to confirm that error handling, retries, and dead-letter queues work as expected - without creating duplicate records or corrupting data.
How do I test syncs at production scale safely?
Use a dedicated sandbox with realistic, anonymized data. Before full deployment, pilot a sync with 5% to 10% of real records over 60 to 90 days to spot edge cases.
Document a rollback plan. Monitor delivery across webhooks, queues, and sync jobs, and set alerts for unexpected silence. Apply rate limits to prevent overload and idempotency keys to prevent duplicates. Review errors and failed webhooks, and resolve issues within 24 hours.
How do I choose a webhook deduplication window?
Log delivery timestamps, HTTP status codes, and response bodies. Use those logs to find the longest gap between duplicate deliveries for the same submission or event. Set the deduplication window slightly longer than that gap to catch late retries, but short enough to keep separate submissions from being treated as duplicates.
Use a distinct submission_id or idempotency key with “update if exists” behavior so duplicate deliveries update existing CRM records instead of creating new ones.
Related Blog Posts
Get new content delivered straight to your inbox

The Response
Updates on the Reform platform, insights on optimizing conversion rates, and tips to craft forms that convert.

Drive real results with form optimizations
Tested across hundreds of experiments, our strategies deliver a 215% lift in qualified leads for B2B and SaaS companies.
