How Historical Data Improves Lead Score Accuracy


I use historical sales outcomes to score leads by what predicts a sale - not just activity. I start with one scoring date and a fixed conversion window, using only information available when each lead was scored.
Here’s my checklist:
- Set clear labels: Separate wins, losses, and pending deals.
- Clean the records: Remove duplicates, fix fields, and link leads to the right outcomes.
- Test the signals: Compare fit, engagement, timing, and source against a simple baseline.
- Check unseen leads: Train on older records, then test on later leads whose outcome windows have closed.
- Measure sales impact: Check conversion, lift, and results at your team’s follow-up capacity.
For example, if selected leads convert at 10% versus 5% overall, that’s 2× lift - not proof that the score caused more sales.
My rule: <u>check what was known at scoring time</u>, test whether scores match results, and audit data changes before retraining.

How Historical Data Improves Lead Scoring
Predictive Lead Scoring with Dynamics 365 Insights: How Your Sales History and Buyer Behavior Tur...
sbb-itb-5f36581
Define Outcomes and Data Windows
Set one outcome, one scoring date, and one conversion window for every record. These rules decide which historical leads enter your training data.
Label Wins, Losses, and Pending Outcomes
Apply labels consistently once the outcome window closes. Track open opportunities separately so they don’t get labeled as losses. Then align the fixed labels with the time window the model will use.
Choose Data Windows That Fit Your Sales Cycle
Choose a window that fits your sales cycle and apply it consistently.
| Analysis period | Purpose | Data volume | Recency / risk |
|---|---|---|---|
| 30 days | High-frequency engagement tracking | Lower volume | High recency; reflects immediate interest |
| 60 days | Medium-term behavior analysis | Moderate volume | Balanced; identifies fading interest |
| 90 days | Standard inactivity cutoff | Higher volume | Lower recency; identifies long-term unengaged leads |
With the window set, clean the records and connect each signal to its outcome label.
Adjust for Product and Sales Process Changes
When pricing, packaging, or lead qualification rules change, record the change date and relabel older records using the new rules. Keep tags that show which process was in place when each lead was scored.
Once the labeling rules are stable, clean the data and build the model inputs.
Clean Lead Data and Link Signals to Outcomes
With outcomes and time windows fixed, create one row per scored contact or account. Include a stable ID, scored_at, eligible inputs, the outcome, and outcome_at.
Once labels are set, remove duplicates, standardize fields, and link each signal to the correct outcome.
Standardize Records and Group Similar Leads
Score contacts for individual follow-up or accounts for shared buying cycles. Group records by outcome, segment, source, stage, and period. Then compare conversion rates, missing data, and exclusions across those groups.
Check class imbalance, too. A large group of nonconverting leads can hide poor detection of wins. These checks help prevent the model from learning from duplicate activity, mislabeled deals, or segment bias.
| Data problem | Accuracy risk | Cleaning action |
|---|---|---|
| Duplicate contacts or accounts | Activity is split or counted twice | Merge verified matches before aggregating activity; preserve history and a merge log |
| Spam, bots, and internal tests | Artificial records distort conversion rates | Remove confirmed nonprospects; log the reason, rule date, and affected segment |
| Unmatched outcomes | Wins get lost or linked to the wrong record | Reconcile contact, account, and opportunity IDs; audit unresolved matches |
| Inconsistent fields or stages | Equivalent records receive different meanings | Standardize titles, state names, country codes, company-size bands, and industry labels; retain original stages, mapped values, and stage-entry dates |
| Missing source or segment | Missing fields can look like real buyer differences | Keep explicit unknown categories; review missingness by group |
After cleanup, turn the records into model inputs tied to specific time windows.
Turn Historical Signals Into Model Inputs
Map inputs into four groups: firmographic fit (industry, company size, role), engagement (visits, downloads, replies), timing (recency), and source (campaign or referral).
Calculate activity backward from scored_at with explicit 7-, 30-, or 90-day lookback windows - not lifetime totals. Use only signals available by scored_at.
Within similar segments and periods, compare each input’s distribution and its relationship to closed-won versus closed-lost outcomes. Test individual signals and combinations against a simple source-only or rules-based baseline. A pattern that works in one segment may fail in another.
The goal is to predict who is most likely to convert, not who engaged most recently. Next, tighten form collection so future records use the same fields, IDs, and timestamps.
Collect Consistent Form Data and Timestamps
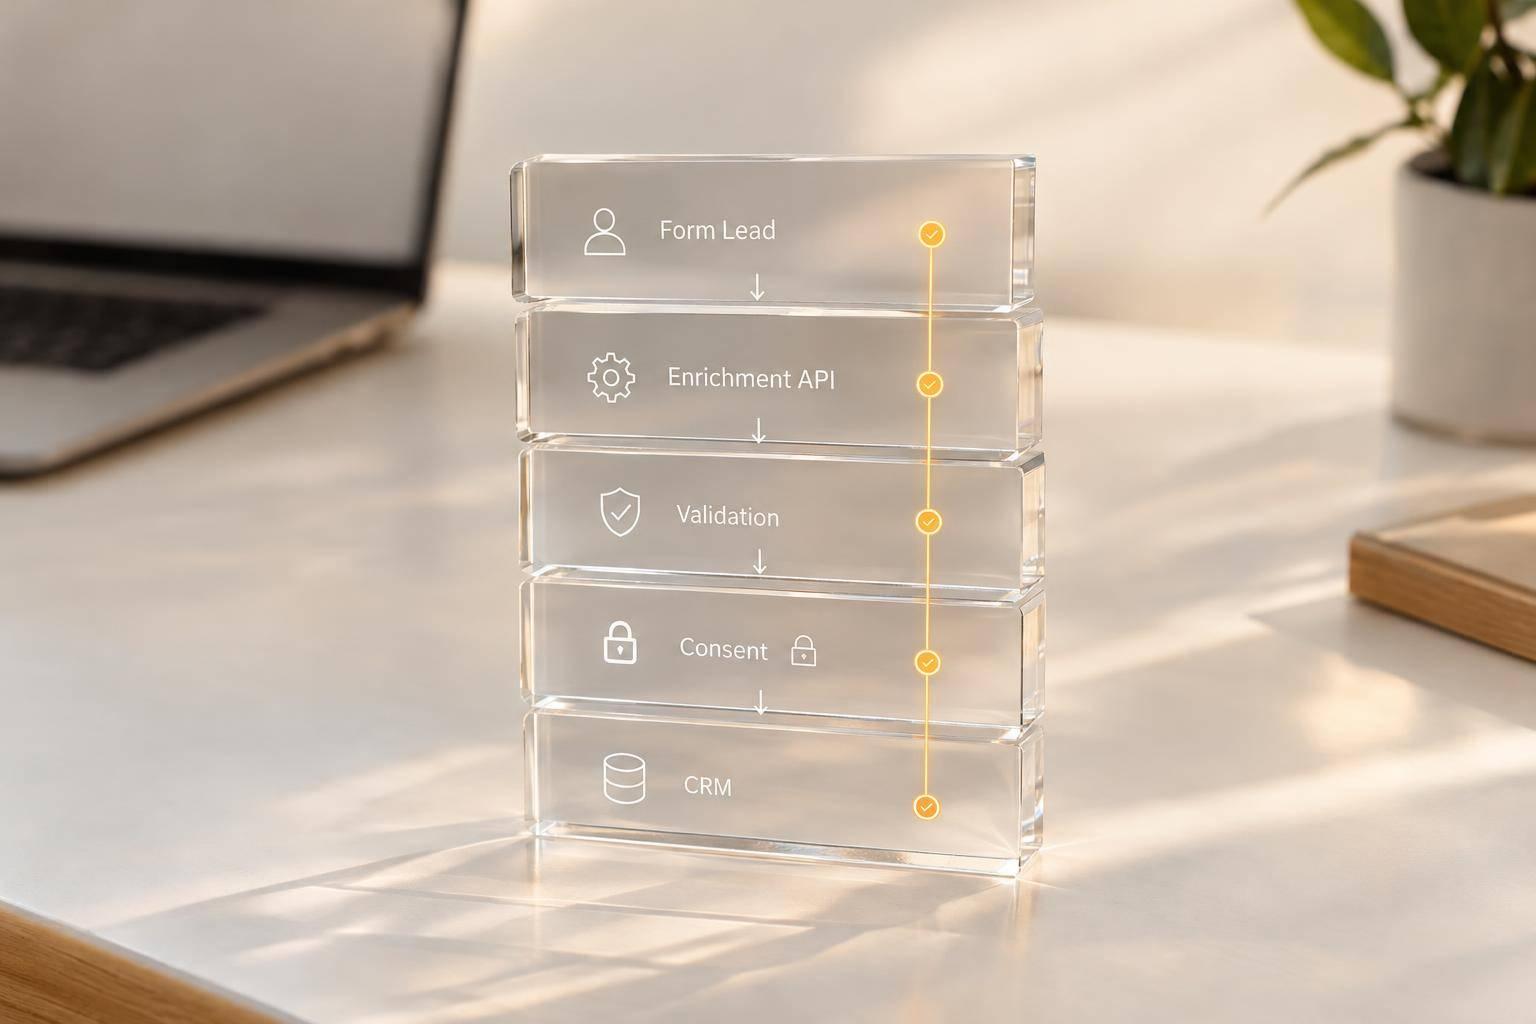
Use Reform’s expert form strategies for conditional routing, email validation, lead enrichment, spam prevention, and CRM integrations to collect cleaner form data. Consistent collection makes later labels and lookback windows reliable.
Map submissions to stable CRM IDs, and retain submission and enrichment timestamps. Email alone is not a permanent identity key. Keep original event timestamps in one time zone rather than using last-modified dates.
Use validation, completion, or abandonment signals only if you can reliably link them to a known lead or account and they were available at scoring. Exclude later enrichment, final deal stages, and post-conversion activity from model inputs. Cleaner collection improves data quality, but every field still needs testing against outcomes.
Train and Test Scores on Unseen Leads
Start with logistic regression as your baseline. The goal is to test historical patterns, not just model them: patterns matter only if they hold on unseen leads. A near-perfect baseline usually points to data leakage.
Split Training and Test Data by Time
Train on older observed cohorts, validate on a later cohort, and save the most recent fully observed cohort for final testing. Use only cohorts whose outcomes have fully matured, with consistent rules for scoring dates and outcome windows.
Fit preprocessing, feature selection, and class-balance adjustments on training data only. Leave the final test set untouched until you’ve fixed your model choices. Keep each account or individual in one partition so duplicates or shared account outcomes don’t cross splits. Preserve chronological order, too, so the test reflects how scoring would work over time.
Measure Ranking, Calibration, and Sales Capacity
Backtest score bands using conversion rate = conversions ÷ leads and lift = band conversion rate ÷ overall conversion rate. At the number of leads sales can handle, measure precision - the share of selected leads that convert - and recall - the share of all conversions included in that selection. False positives waste follow-up time; false negatives mean missed converters.
ROC-AUC measures ranking across thresholds; 0.5 means random guessing. When conversions are rare, also report precision-recall metrics. A strong overall ranking can still hide poor results among the leads selected for follow-up. These measures test whether the score helps sales, rather than just looking good on paper.
Calibration checks whether predicted probabilities match observed outcomes. A 0–100 score isn’t a probability unless it’s explicitly calibrated. Report uncertainty alongside your results.
Compare the New Model With Your Current Score
Compare both scores using the same test records, conversion window, and sales capacity limit. Check whether the new score improves ranking, precision, and calibration under those same constraints. Assess calibration only when probabilities are available.
| Measure | Current score | New model |
|---|---|---|
| Band conversion | Observed rate by band | Observed rate using matching band sizes |
| Lift | Band lift against the test-cohort rate | Band lift against that cohort rate |
| Precision at capacity | Conversions ÷ selected leads | Calculated at the fixed capacity limit |
| Recall at capacity | Selected conversions ÷ all test-cohort conversions | Calculated at the fixed capacity limit |
| Calibration | Predicted versus observed rates | Evaluated using matching probability bands |
Once the model is in production, track these same measures as outcomes arrive.
Conclusion: Keep Scores Accurate as Outcomes Arrive
After testing on unseen leads, continue checking scores against newly matured outcomes. Historical data improves lead scores only when labels, timestamps, and outcome windows stay consistent - and the model is checked again as outcomes mature.
Monitor Results and Update the Model
Track score distributions, conversion by band, calibration when probabilities are available, false positives, and pipeline created as outcomes mature. Check whether high scores help sales teams prioritize leads.
Investigate before retraining or changing thresholds. Compare current feature and score distributions with the training baseline. Then audit missing fields, form changes, lifecycle definitions, and CRM integration failures. Shifting scores may point to a change in lead mix. If conversion falls after outcomes mature, examine conversion drift and sales execution.
Keep a Checklist for Each Model Version
Before rescoring or changing thresholds, record the model’s version, owner, training dates, scoring time, input fields, transformations, outcome definitions, conversion window, exclusions, thresholds, and test metrics. Keep deployment dates, known issues, approval owners, and rollback instructions so each change can be traced.
| Signal or data condition | Validation check | Warning sign | Recommended action |
|---|---|---|---|
| Win, loss, and pending labels | Confirm outcome-window completion | Pending leads counted as losses | Rebuild labels before testing |
| Input timestamps | Verify availability at scoring time | Fields populated after sales contact | Remove later information |
| Form and CRM fields | Check missingness and mappings | Missing values rise after a form change | Repair mappings before rescoring |
| Historical lead mix | Compare current lead mix with training mix | Training data reflects outdated processes | Select representative cohorts |
| Score bands | Review mature conversion by band | High scores show activity but little progression | Investigate targeting, routing, and follow-up |
Before changing live scores, audit one fully matured cohort. Confirm what was known at scoring time, which outcomes matured, and whether the score helped sales teams prioritize leads.
FAQs
How much historical data do I need to score leads?
Aim for at least 80 historical leads, ideally split between 40 closed-won deals and 40 lost deals. That balance helps your lead scoring model spot patterns and predict outcomes for new leads.
Start with clean, structured demographic, firmographic, and behavioral data. Reform can help validate submissions, block spam, and enrich lead records. Test your model against known outcomes to keep scoring thresholds in line with your business goals and sales performance.
How should I handle leads that convert after my window closes?
Leads that convert after your window closes still offer useful feedback. Don’t ignore them. Look into why they converted late: did you miss intent signals or incorrectly label them as low-quality?
During quarterly audits, compare these cases with your model’s predictions. Adjust point weights or time-based thresholds as needed. Make sure your CRM records every interaction so gaps in activity data don’t hide useful signals.
Should I build separate scoring models for different segments?
The right approach depends on your business goals and how complex your lead data is. A single model is often a good starting point. Separate models may make sense if industries or company sizes differ sharply in conversion patterns, high-intent behaviors, or firmographic indicators.
Review conversion data and sales feedback regularly to check whether segment-specific models improve predictive accuracy.
Related Blog Posts
Get new content delivered straight to your inbox

The Response
Updates on the Reform platform, insights on optimizing conversion rates, and tips to craft forms that convert.

Drive real results with form optimizations
Tested across hundreds of experiments, our strategies deliver a 215% lift in qualified leads for B2B and SaaS companies.
