How Queue Workers Handle Form API Spikes


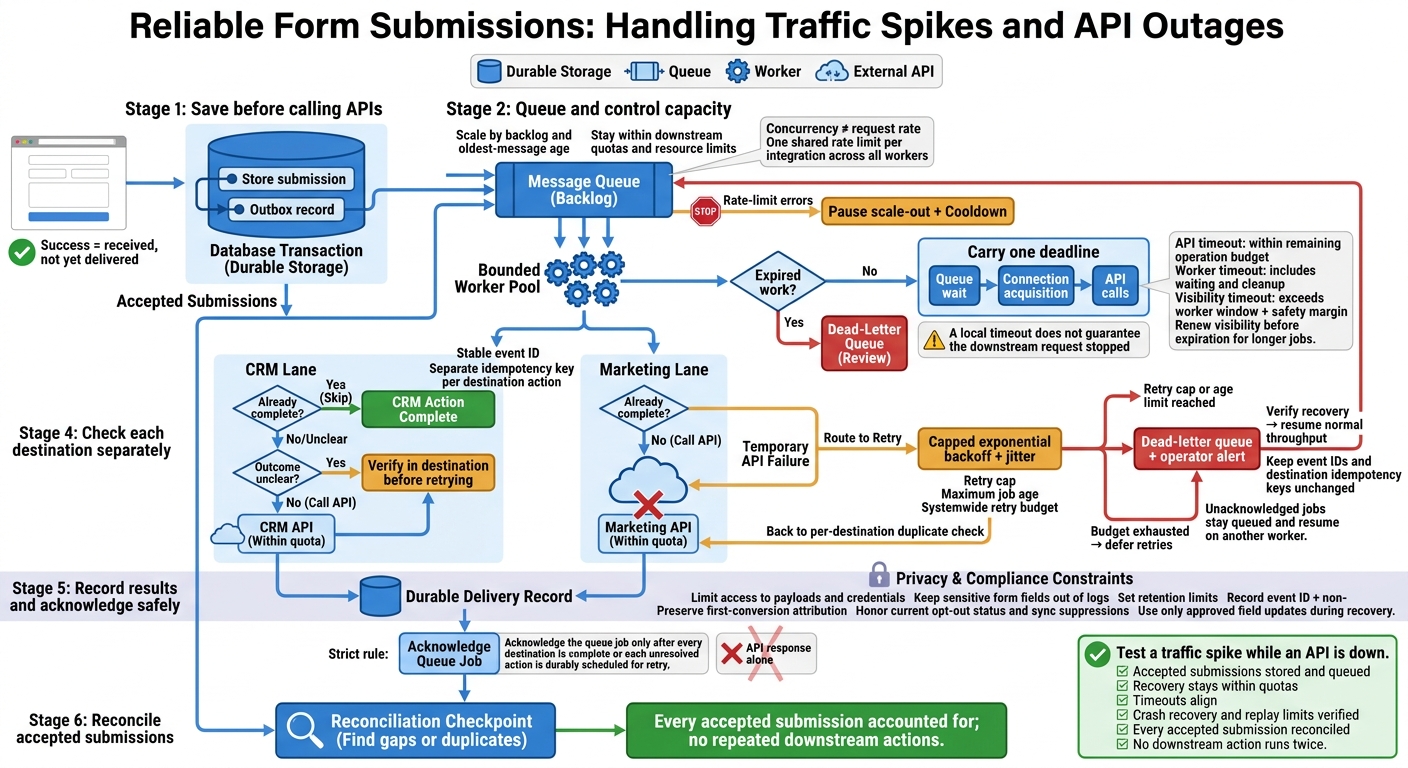
I save form submissions before calling any API. I store each submission and its outbox record in one database transaction, then return success. That means received, not yet delivered.
To handle a spike without losing leads or repeating actions, I focus on four things:
- Worker limits: Scale by backlog and message age, while keeping request rates within each API’s quota.
- Timeouts and retries: Align API, worker, and message visibility windows. Use delayed retries with clear attempt and age limits.
- Duplicate checks: Keep stable IDs and separate delivery records for each destination, so a retry doesn’t repeat a completed action.
- Recovery and privacy: Protect lead data, review failed jobs, and compare accepted submissions with downstream records.
My final check: <u>test a traffic spike while an API is down</u>, then confirm that every accepted submission is accounted for after recovery - with no repeated downstream actions.
How Queue Workers Handle Form API Spikes
Building a Scalable Queue System with NestJS & BullMQ & Redis
sbb-itb-5f36581
Set Worker Capacity and Message Visibility
Autoscaling controls how fast workers clear burst traffic from the queue. Concurrency limits simultaneous jobs; visibility hides claimed messages from other workers. Base both settings on measured processing times, delivery targets, and downstream quotas - not fixed defaults.
Scale Workers by Backlog and Message Age
Track queue depth, oldest-message age, processing time, errors, and resource use together. No single metric tells the whole story.
| Signal | Decision |
|---|---|
| Queue depth keeps growing | Add workers only within downstream quotas and resource limits. |
| Oldest-message age approaches the delivery target | Scale before the remaining processing budget runs out. If age reaches the target, send expired work to a dead-letter queue before calling APIs. |
| Concurrency rises without higher throughput | Check busy HTTP slots, database connections, and stalled calls before adding workers. |
| Rate-limit errors increase | Pause scale-out and apply a cooldown. More workers may make throttling worse. |
Set minimum and maximum worker counts, then test burst recovery and a downstream API outage. Scaling should shrink the backlog without increasing throttling. During scale-in, stop claiming jobs and release connections in finally cleanup.
Keep Concurrency Within API Quotas
Concurrent jobs and downstream request rates are separate limits. Start with low concurrency. Increase it only while measured latency and errors stay acceptable. Apply one shared rate limit per CRM or marketing integration across all workers.
Align API, Worker, and Visibility Timeouts
Carry one deadline through queue wait, connection acquisition, and API calls. Reject expired work, and keep claimed messages hidden while they’re being processed.
Set API and worker timeouts so the visibility timeout exceeds the worker window plus a safety margin. Renew visibility for longer jobs. A local timeout doesn’t guarantee that the downstream request has stopped, so track lingering connections too.
| Control | What it bounds | Setting rule |
|---|---|---|
| API timeout | One downstream call | Keep it within the operation’s remaining budget. |
| Worker timeout | One job’s execution window | Bound total execution, including waiting and cleanup. |
| Visibility timeout | How long a claimed message stays hidden | Exceed the worker window plus a safety margin; renew before expiration when needed. |
| Concurrency limit | Simultaneous jobs or dependency calls | Apply dependency-wide limits across every worker instance. |
Retries handle jobs that still fail after capacity and timeout tuning.
Set Retry Limits and Handle Failed Jobs
Classify Errors and Set Retry Backoff
Once you’ve tuned capacity and timeouts, your retry policy decides what happens when jobs still fail. Retry temporary failures with capped exponential backoff and jitter: increase the delay after each attempt, set a maximum delay, and add random timing so retries don’t hit a recovering API all at once.
Set Retry Budgets and Replay Failed Jobs Safely
Set a retry cap, a maximum job age, and a systemwide retry budget. These limits keep failed jobs from crowding out new submissions. When the retry budget runs out, defer retries.
Move jobs that reach the retry cap or age limit to a dead-letter queue, and alert operators for offline review. After fixing the cause, replay a small batch to check that the system has recovered before returning to normal throughput.
Prevent Duplicate CRM and Marketing Actions
A timeout or crash can cause a job to run again, so each destination needs its own duplicate check. A retry may need to repeat a failed marketing action without repeating a completed CRM update.
Use Stable Event IDs and Idempotent Operations
Use the saved submission as the source of truth. Give it a stable event ID, and create a separate idempotency key for each destination action. Keep these keys unchanged across retries and replays.
Before calling an API, check the delivery record. If the outcome is unclear, verify what happened in the destination system before retrying.
A retry should never overwrite first-conversion fields or repeat an action that already succeeded. During recovery, use only approved field updates. Apply suppression syncs to keep opt-out status consistent across connected systems.
Save Delivery Status Before Acknowledging Jobs
Store each destination’s delivery status in durable storage. Acknowledge the queue job only after every destination is complete or each unresolved action is durably scheduled for retry.
Protect Lead Data and Check Delivery Records
Limit access to payloads and credentials, keep sensitive form fields out of logs, and set retention limits. For every destination attempt, record the event ID and a non-sensitive outcome.
Compare accepted submissions with downstream records to find gaps or duplicates. Preserve first-conversion attribution and honor the current opt-out status so replays don’t overwrite lead history or restart unwanted campaigns.
Conclusion: Test the Full Spike-Handling Flow
After tuning workers, timeouts, and retries, test a spike in form submissions while the downstream API is down. Check that accepted submissions are stored, queued, and processed after recovery without exceeding quotas. Also verify that timeouts align.
Next, test crash recovery, replay limits, and reconciliation. Confirm that unacknowledged jobs stay queued and resume on another worker. Pass only when every accepted submission is reconciled and no downstream action runs twice.
Document endpoints, credentials, message TTLs, backoff intervals, concurrency limits, and visibility timeouts. Set pass/fail criteria for payload validation, Close CRM update confirmation, TLS handshake, and consent record matching. Define alert thresholds for oldest-message age and delivery failures. Assign owners for integration, compliance/privacy, and on-call engineering.
FAQs
How do I estimate how quickly a backlog will clear?
Compare worker throughput against the number of pending jobs, and track queue depth and P95 job completion time. If the queue keeps growing, workers aren’t keeping up with incoming traffic.
If the backlog continues to grow, check retry rates and the age of the oldest jobs. These metrics can signal that your sync process is falling short of its performance targets [3][4].
Which API errors should I retry?
Retry only temporary errors: network timeouts, connection resets, HTTP 500, 502, 503, 504, and rate limits (HTTP 429). Send permanent failures straight to a dead-letter queue.
Do not retry HTTP 400 (malformed JSON or invalid fields), 403 (permissions), or 404 (missing resource) errors. For HTTP 401 (unauthorized), try one token refresh before abandoning the request.
How do I prevent duplicates without API idempotency support?
Use an upsert strategy with a stable external identifier, such as a submission ID that’s distinct for each submission or an email address. Before writing to your CRM, look for an existing record with that identifier. If you find one, update it. If not, create it.
Store each successfully synced event ID in a local database or cache. Before any write, check whether that event ID has already been synced. If it has, skip the write.
Related Blog Posts
Get new content delivered straight to your inbox

The Response
Updates on the Reform platform, insights on optimizing conversion rates, and tips to craft forms that convert.

Drive real results with form optimizations
Tested across hundreds of experiments, our strategies deliver a 215% lift in qualified leads for B2B and SaaS companies.
